
Multimodal Models
One model that sees, hears and reads.
The newest models do not handle only text. They can look at a photograph, listen to a recording, and read a document, all in one conversation. In this lesson, you will learn what multimodal means, and how it opens up a new world of uses.
- More than text
- Seeing, hearing and reading together
- A new world of uses
One shared language of tokens
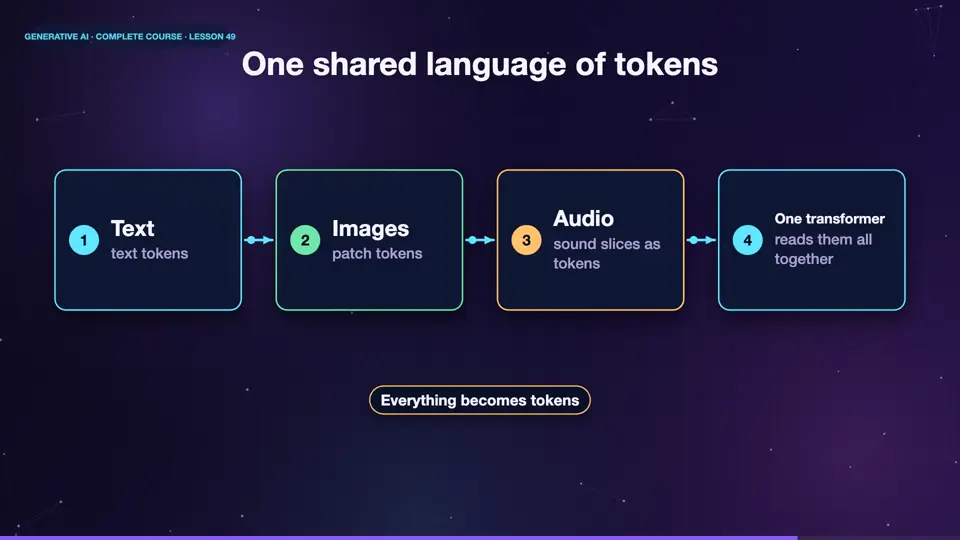
The trick is to turn every kind of data into tokens. Text becomes text tokens. An image is cut into little patches, and each patch becomes a token. Audio is cut into small slices, and each becomes a token. A single transformer then reads all these tokens together, in one sequence, so it can connect what it sees, with what it reads, and hears.
- Texttext tokens
- Imagespatch tokens
- Audiosound slices as tokens
- One transformerreads them all together
What multimodal models can do
This unlocks wonderful uses. Describe a photo, for someone who cannot see it. Read a handwritten note, or a messy receipt. Explain a chart, or a diagram. Help fix a problem, from a screenshot. Translate a menu, from a picture. Answer questions about a video. And hold a spoken conversation, in real time. Just point your camera, and ask.
Strengths and cautions
As always, use it with care. Multimodal models can misread small text, miscount objects, or invent details in an image. Do not rely on them alone, for medical images, or legal documents. And be careful about privacy. Photos can contain faces, addresses, and other personal details. Check what a tool does with the pictures you upload.
Strengths
- Understands pictures and text together
- Great for accessibility
- Fast first reading of documents
Cautions
- May misread or invent details
- Not a doctor or a lawyer
- Photos can reveal private information
Summary
Excellent. Multimodal models turn text, images, and audio into tokens, and read them together. They can describe, read, explain, and converse, but they can also misread, so verify what matters, and protect privacy. Next, we learn how to adapt models to your own needs, through fine tuning, and running them locally.
Key takeaways- Everything becomes tokens
- See, hear, read, and talk
- Verify and protect privacy