
Fine-tuning and Instruction Tuning
From text predictor to helpful assistant.
A freshly pre-trained model is a brilliant text predictor, but a poor assistant. Ask it a question, and it may continue with more questions, instead of an answer. In this lesson, you will see how a raw model is taught to follow instructions.
- A base model only continues text
- An assistant must follow instructions
- Instruction tuning teaches this
A base model versus an assistant
Here is the difference. If you give a base model the text, what is the capital of France, it may simply continue the pattern, with more quiz questions, as if it were a worksheet. It predicts likely text, and a worksheet is likely text. An assistant, after instruction tuning, understands that you want an answer, and replies, the capital of France is Paris.
Instruction tuning
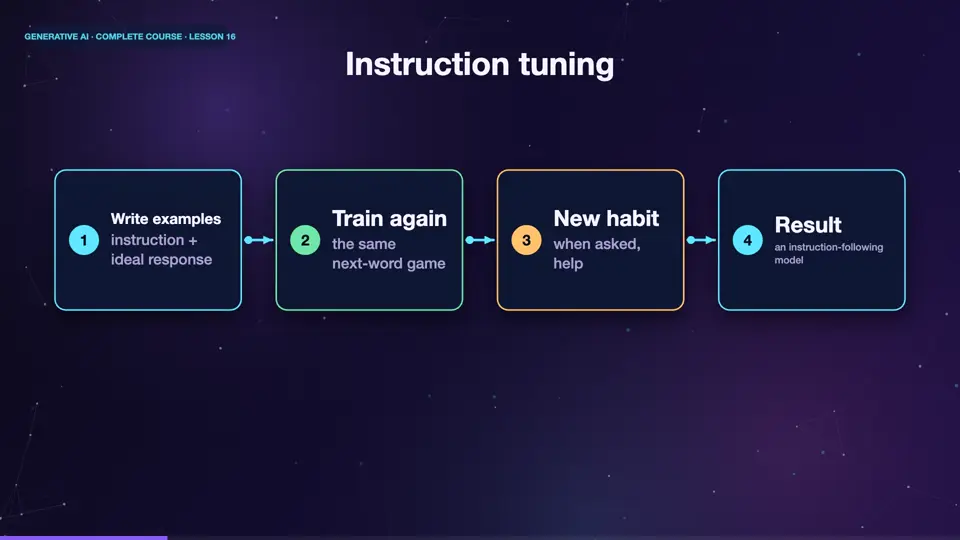
Instruction tuning is a second round of training, on a much smaller dataset. People write thousands of examples of good behaviour. Each example has an instruction, and an ideal response. Summarise this article. Translate this sentence. Explain this concept. The model trains on them, using the same next word game. Now it learns a new pattern, when a person asks for something, I should help.
- Write examplesinstruction + ideal response
- Train againthe same next-word game
- New habitwhen asked, help
- Resultan instruction-following model
Fine-tuning for your own needs
The same idea lets you adapt a model, for your own needs. This is called fine-tuning. A law firm may fine tune on its contracts. A hospital on its clinical notes. A company on its own support conversations, to match its tone. You do not train from scratch. You start with a foundation model, and teach it a little more. It is far cheaper, and often a very effective way to specialise.
Summary
Good. Instruction tuning teaches a raw model to follow instructions, using a small set of high quality examples. Fine tuning adapts a model to your own field, at a fraction of the cost. Next, an even more important step, teaching the model what humans actually prefer.
Key takeaways- Base models continue, assistants answer
- Instruction tuning: examples of good behaviour
- Fine-tuning specialises a model cheaply